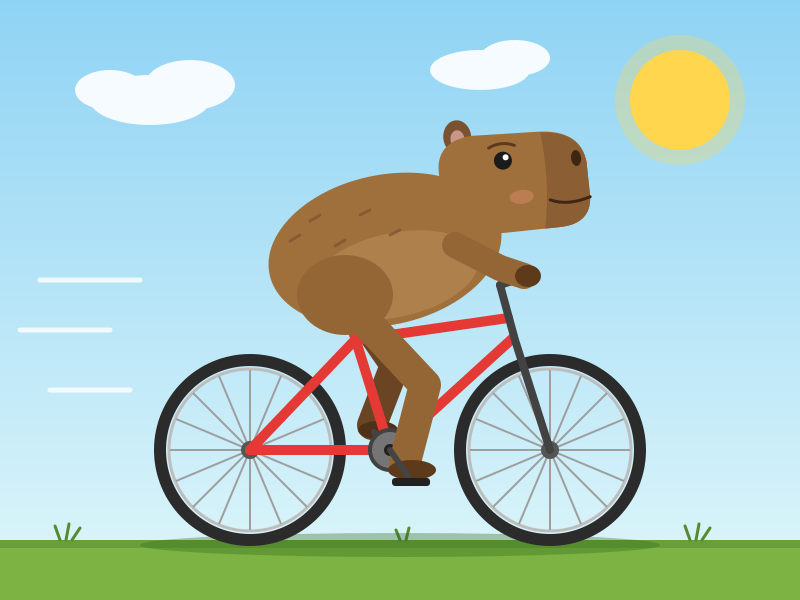
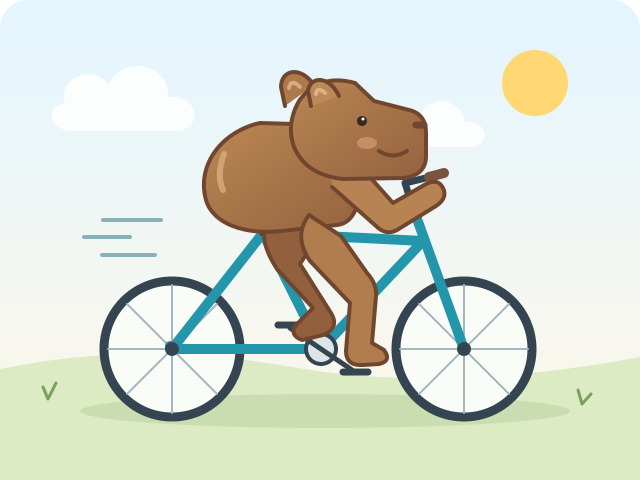
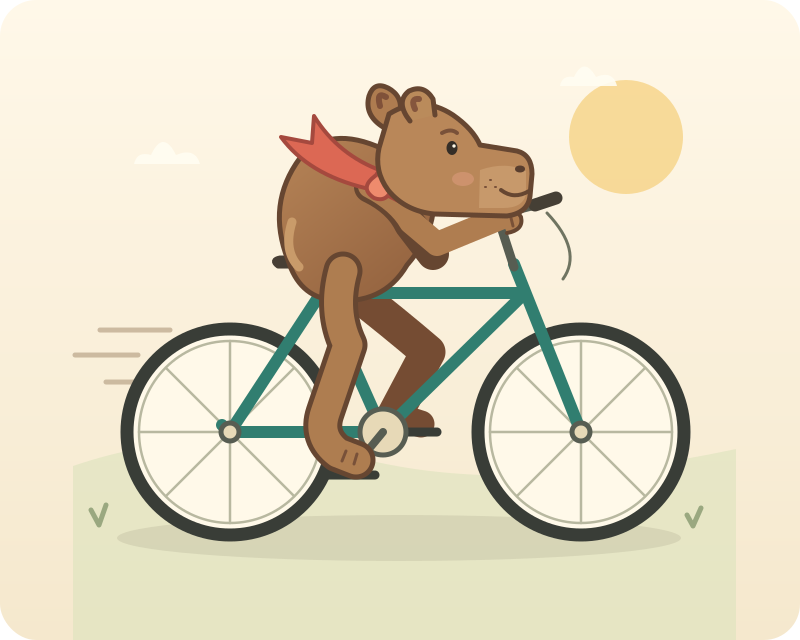
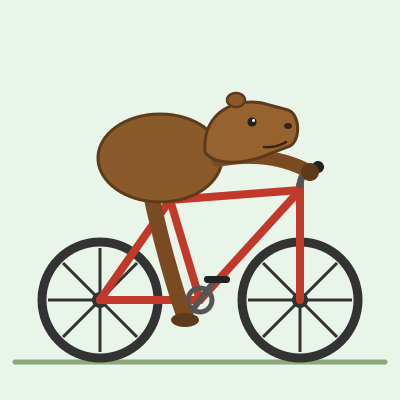
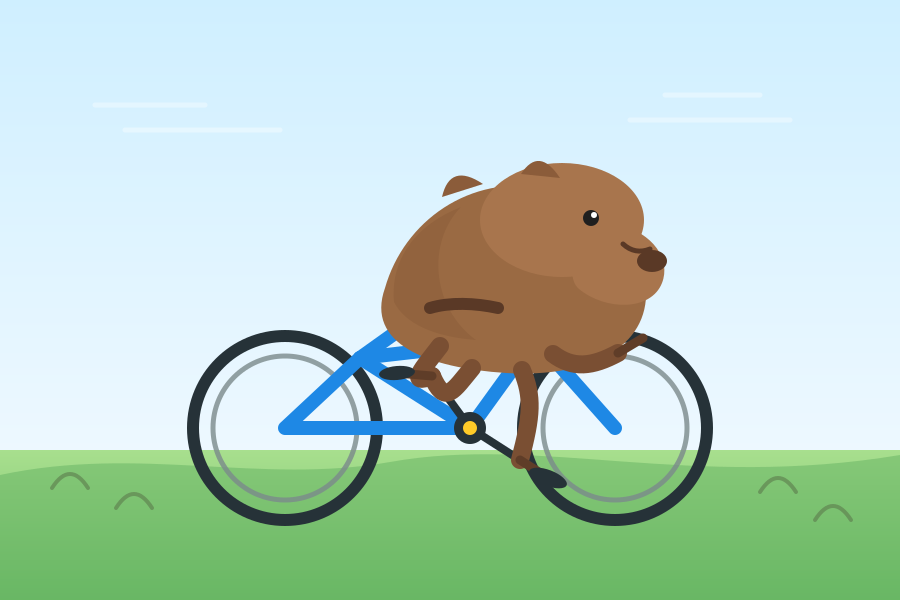
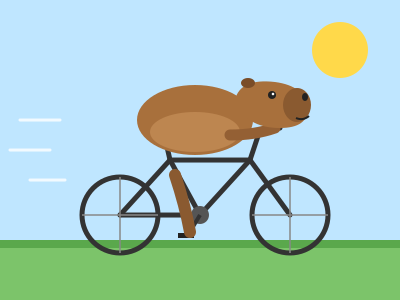
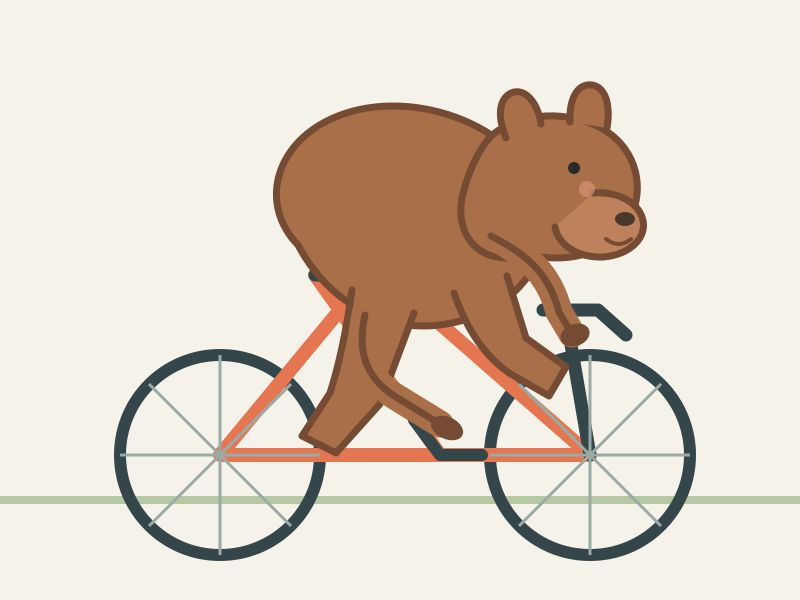
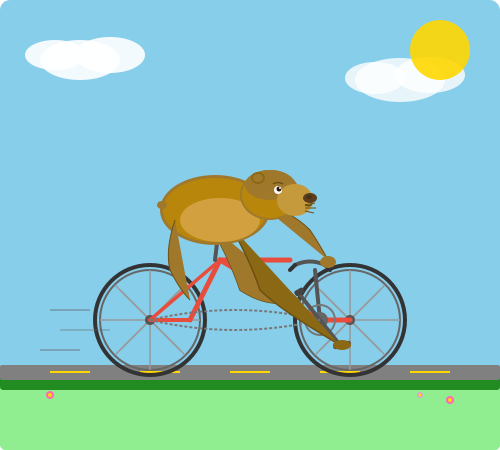
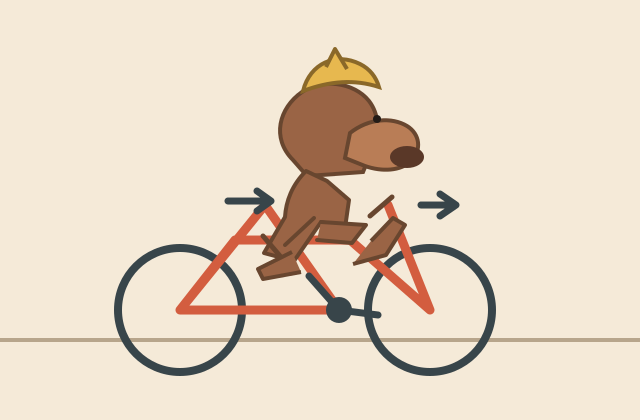
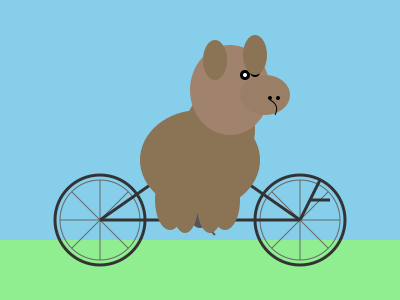
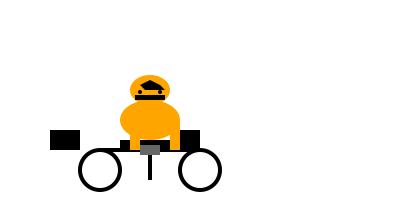
Podium
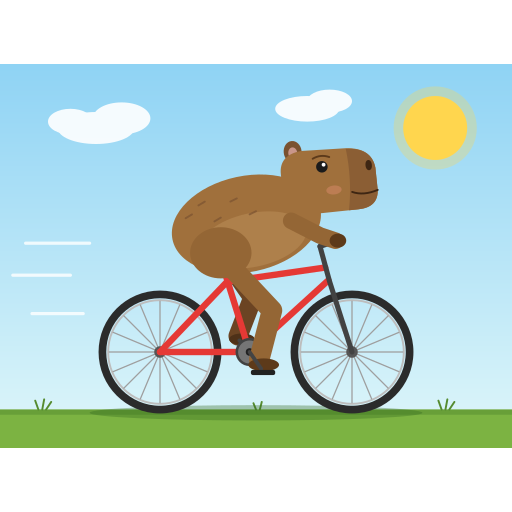
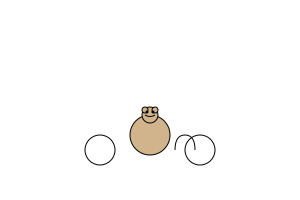
1º
Claude Fable 5.1
Claude subscription 97%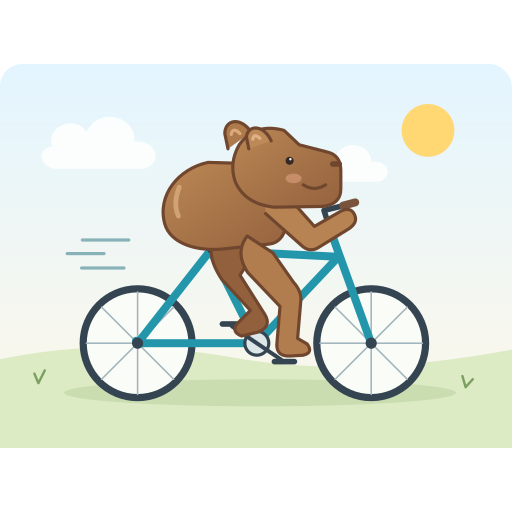
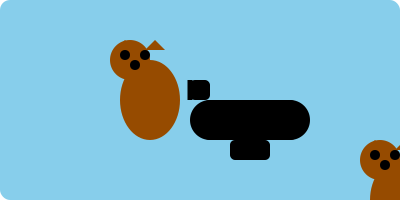
2º
GPT-6.1 Sol
ChatGPT/Codex subscription 94%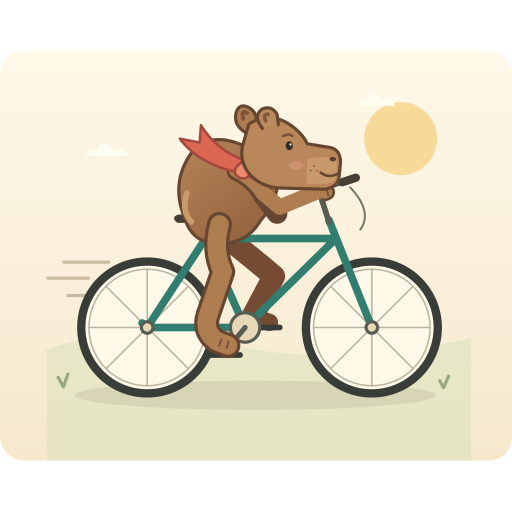
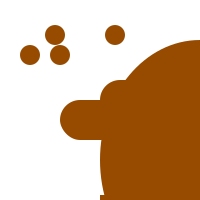
3º
GPT-6 Astra
ChatGPT/Codex subscription 91%How it was measured
- 19 models: 10 running on the computer itself (Ollama) and 9 through the subscription (Claude Code and Codex). No paid API.
- One attempt per model, on 2026-10-05. Run it again and the drawing changes: it is a snapshot, not a verdict.
- Main judge: claude-sonnet-5-5. It saw 306 matchups, each pair in both orders (left/right), without names.
- The left side won 50% of the time (50% = no position bias).
- A second judge (gpt-6-luna) redid 64 random matchups and agreed on 92%.
- Ranked by win rate. ELO (average over 200 shuffled orders) is shown alongside for comparison.
Full ranking
| # | Drawing | Model | Runs on | Wins | Rate | ||
|---|---|---|---|---|---|---|---|
| 1 | | Claude Fable 5.1claude-fable-5-1 | Claude subscription | 33/34 | 97% | ||
| 2 | | GPT-6.1 Solgpt-6.1-sol | ChatGPT/Codex subscription | 32/34 | 94% | ||
| 3 | | GPT-6 Astragpt-6-astra | ChatGPT/Codex subscription | 31/34 | 91% | ||
| 4 | 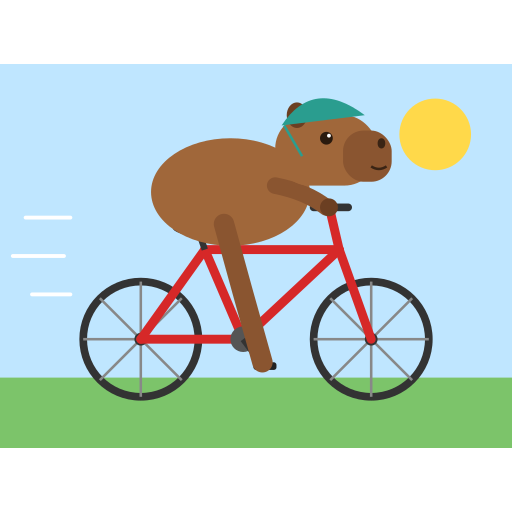 | Claude Opus 5.5claude-opus-5-5 | Claude subscription | 28/34 | 82% | ||
| 5 | 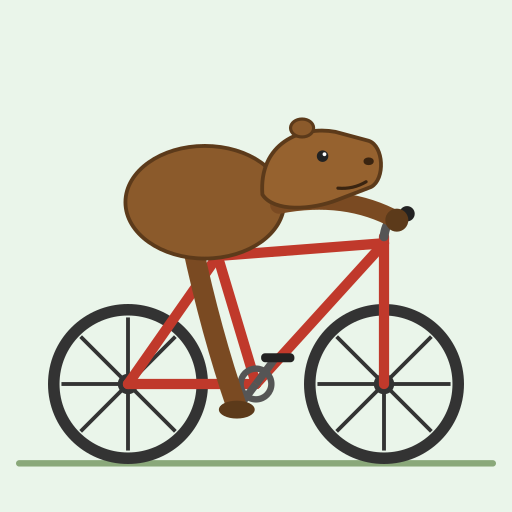 | Qwen 3.8 27Bqwen3.8:27b | your own PC | 25/34 | 74% | ||
| 6 | 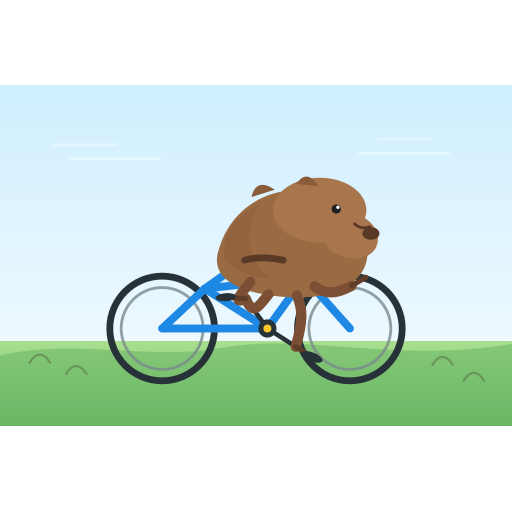 | GPT-5.5gpt-5.5 | ChatGPT/Codex subscription | 24/34 | 71% | ||
| 7 | 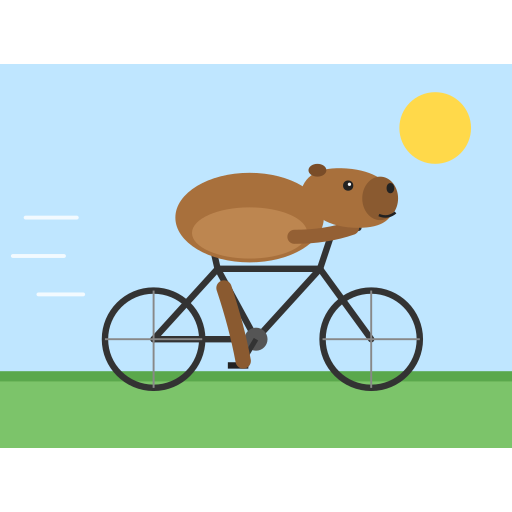 | Claude Sonnet 5.5claude-sonnet-5-5 | Claude subscription | 22/34 | 65% | ||
| 8 | 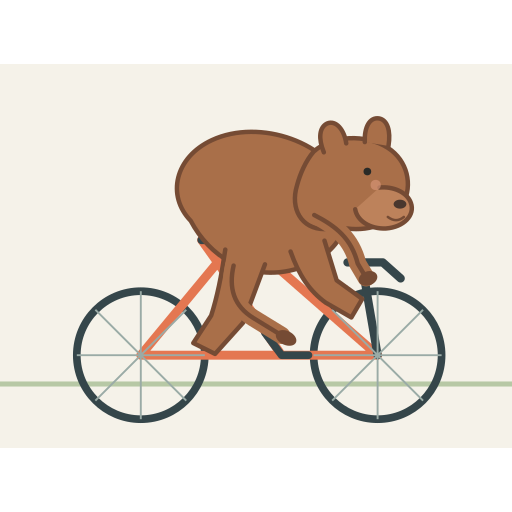 | GPT-6 Solgpt-6-sol | ChatGPT/Codex subscription | 20/34 | 59% | ||
| 9 | 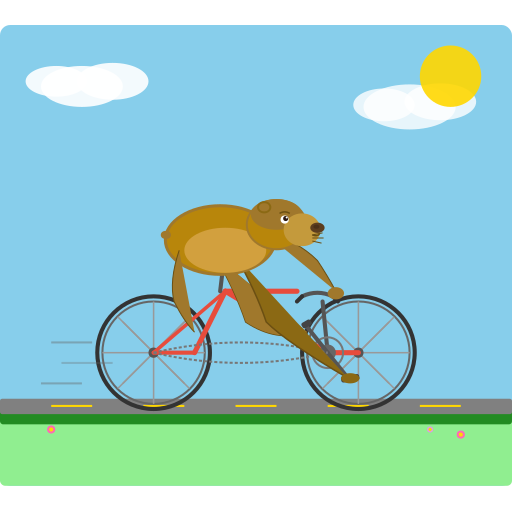 | Qwen 3.6 35B-A3Bqwen3.6:35b-a3b | your own PC | 18/34 | 53% | ||
| 10 | 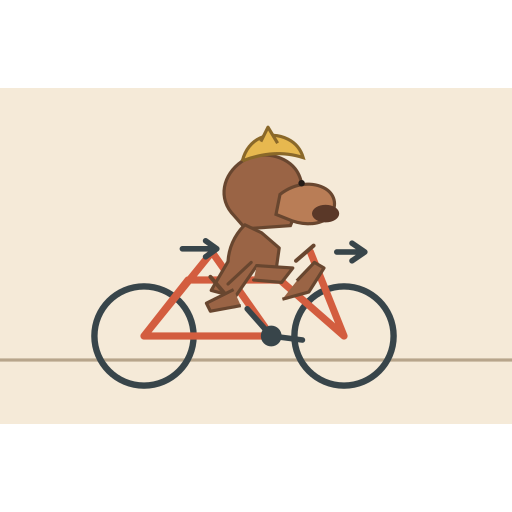 | GPT-6 Lunagpt-6-luna | ChatGPT/Codex subscription | 17/34 | 50% | ||
| 11 | 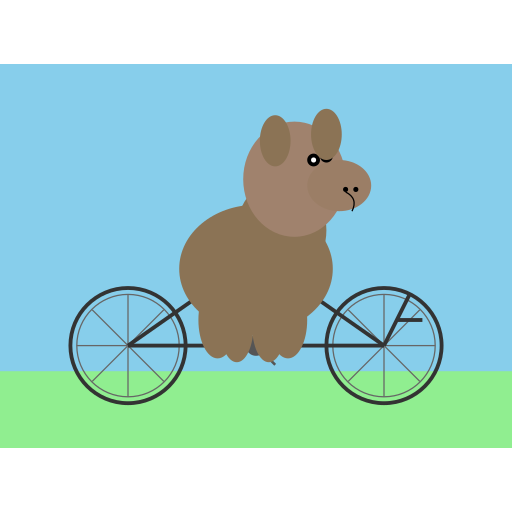 | Claude Haiku 4.5claude-haiku-4-5-20251001 | Claude subscription | 14/34 | 41% | ||
| 12 |  | DeepSeek R1 14Bdeepseek-r1:14b | your own PC | 12/34 | 35% | ||
| 13 |  | Qwen 3 30Bqwen3:30b | your own PC | 10/34 | 29% | ||
| 14 |  | Llama 3.1 70Bllama3.1:70b | your own PC | 8/34 | 24% | ||
| 15 | 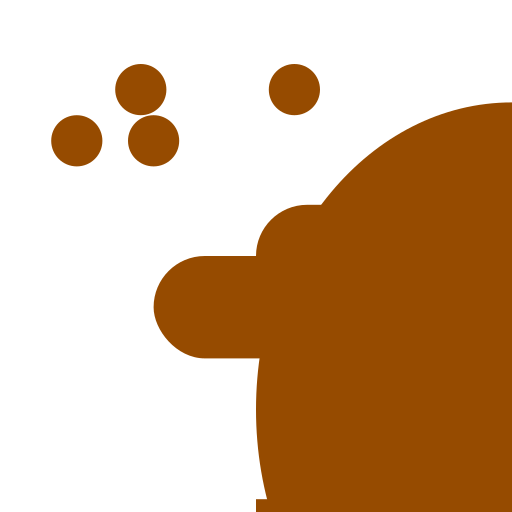 | Llama 3.2 3Bllama3.2:latest | your own PC | 5/34 | 15% | ||
| 16 | 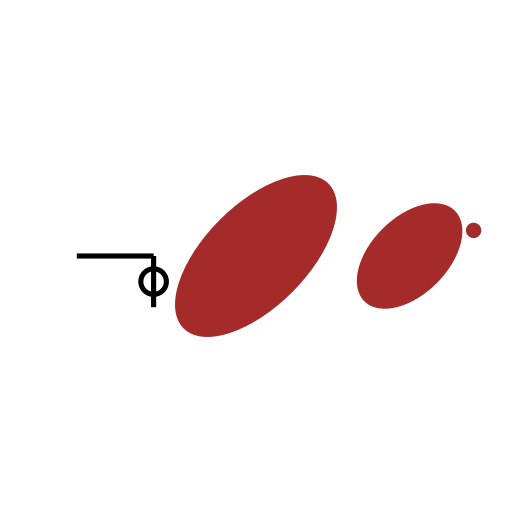 | Qwen 2.5 14Bqwen2.5:14b | your own PC | 4/34 | 12% | ||
| 17 | 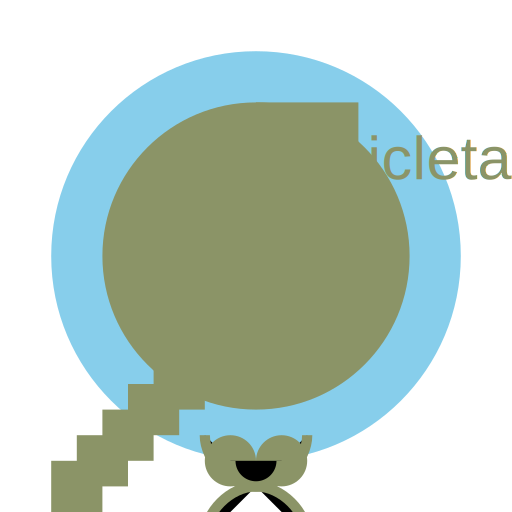 | Llama 3.1 8Bllama3.1:8b | your own PC | 2/34 | 6% | ||
| 18 | 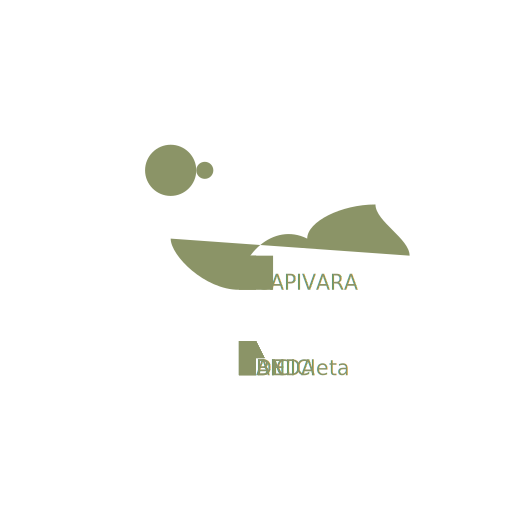 | Llama 3 8Bllama3:latest | your own PC | 1/34 | 3% | ||
| – | Command R 35Bcommand-r:35b | your own PC | no valid SVG | ||||
What about local models?
The best model running on the computer itself was Qwen 3.8 27B, ranked 5 of 18. The weakest cloud model ranked 11.
The most lopsided matchup
First place against last place. What the judge wrote (in Portuguese):
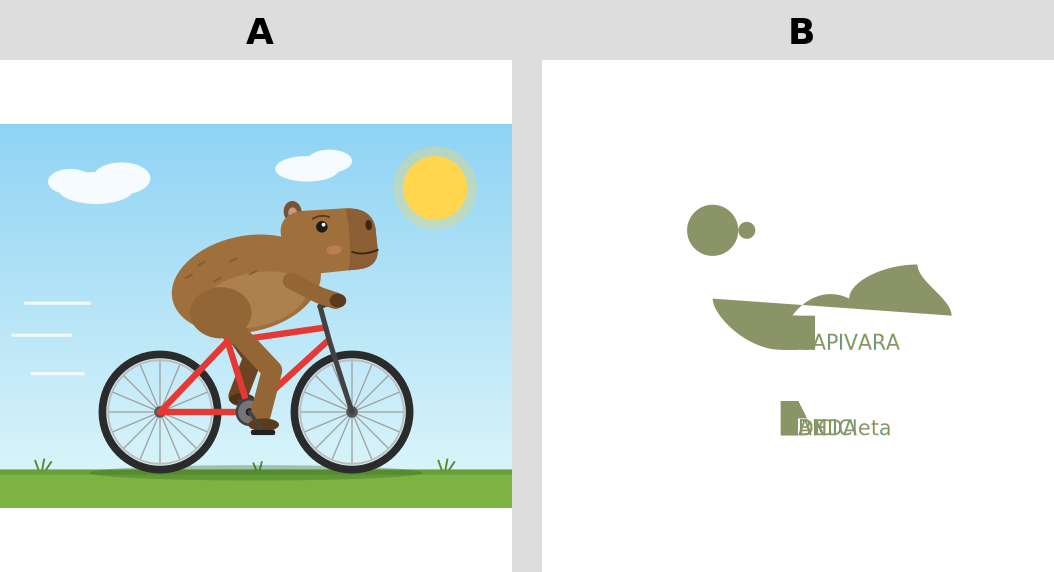
A mostra uma capivara reconhecível pedalando uma bicicleta bem desenhada, numa cena completa, enquanto B é só um conjunto de formas abstratas com texto sobreposto, sem capivara nem bicicleta identificáveis. (judge wrote in Portuguese)
Every drawing