⚙️ What an agent loop is
One agent loop is just an AI that reasons what to do, acts, e observes the result—again and again, until the goal is reached. Nothing magical: three beats that repeat toward a goal, until a "done?" check says to stop.
Read the diagram: starting from the goal, the agent thinks (reason), acts with a tool (act), and reads what happened (observe). If it isn't finished yet, it goes back to the beginning. When the "done?" check passes, it stops.
🧩 The sentence that sums it all up
"An agent loop is an LLM that calls tools, checks the result, and repeats toward a stated goal—until it’s ready or you stop it." Keep that sentence: it’s the answer key that fits the 11 definitions out there.
🖼️ The 4 figures that get confused
Watch five videos and you’ll see five different figures. They’re the same concept from different angles. These are the four you’ll encounter most often—and the confusion isn’t your fault.
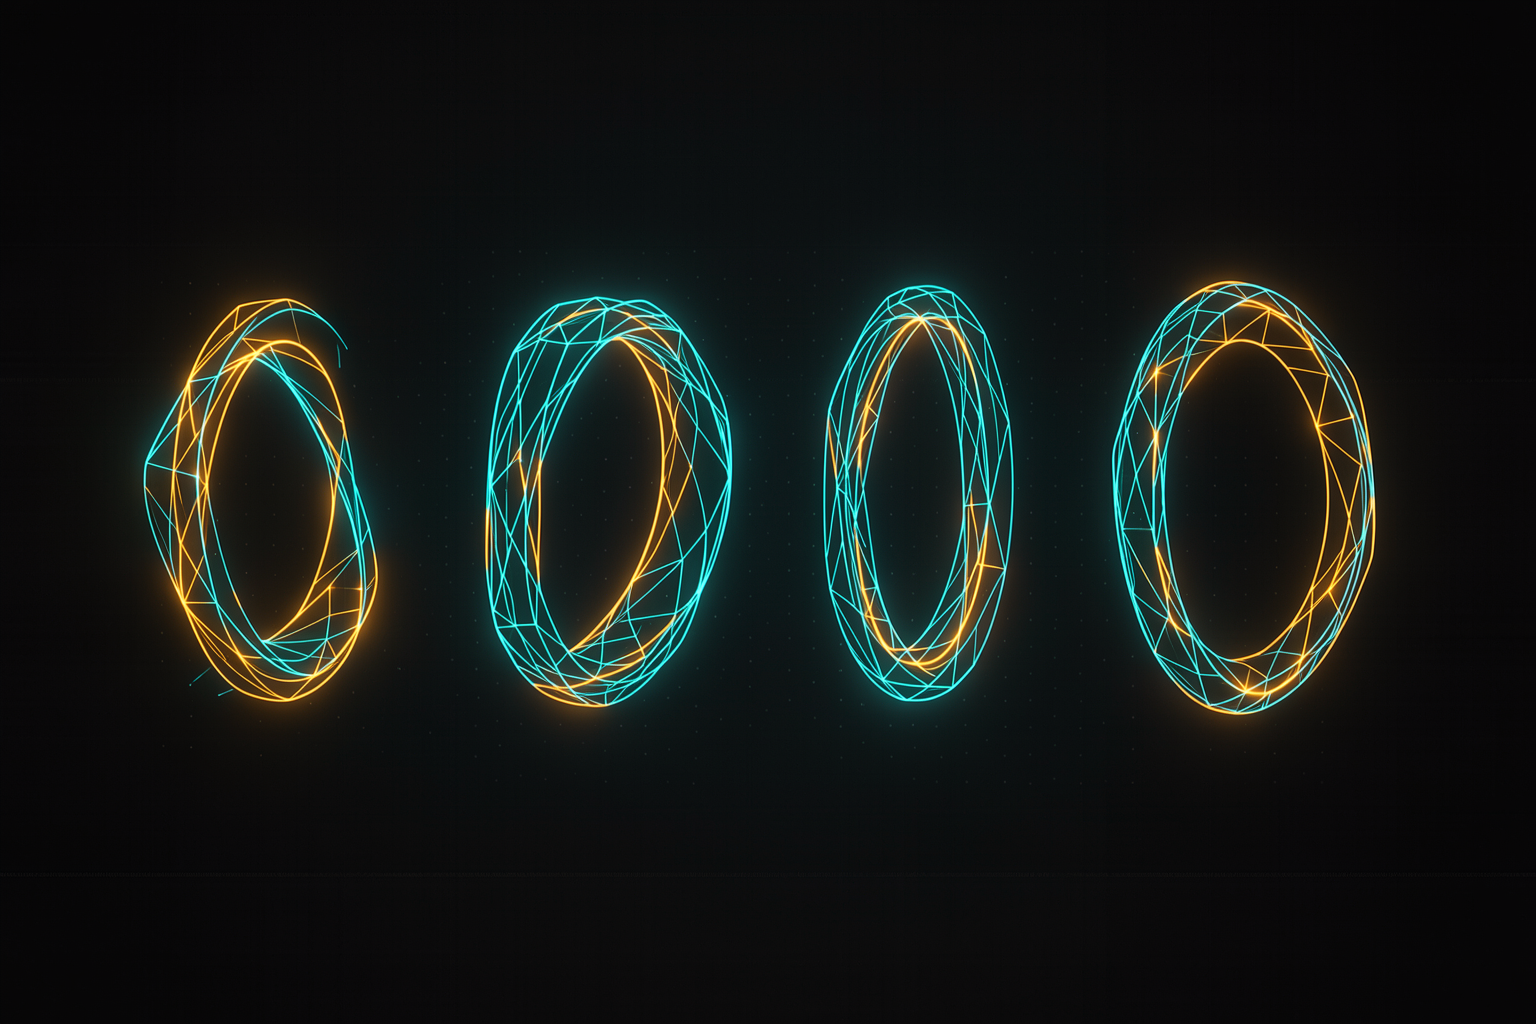
What to look at: four drawings, just one plant. Beginners think they’re four different things; they’re four pictures of the same object.
🔵 "Think → Act → See"
The same three beats, using older terminology (the ReAct paper).
🟢 "Model uses tools, on repeat"
The simplest version: a model calling tools without stopping (Anthropic).
🟡 "Runs on its own"
The same loop, but left running unsupervised toward a goal (AutoGPT).
🟣 "One boss, several helpers"
A lead agent assigns tasks to subagents (multi-agent).
The key insight: the design doesn't matter—they all collapse into the same skeleton. Learn the skeleton and any new diagram will be obvious.
👁️ The “observe” beat
Of the three beats, the middle one in the name — observe — this is what makes the loop actually work. It’s the moment when the agent reads its own result instead of assuming it worked.
What to look at: the agent reads the result, and the information feeds into the next decision. Without that read, it’s blind.
✗ No observation
The agent acts, assumes it worked, and moves on. The result: polished, confident, and wrong — and it calls it “done.”
✓ Observing
The agent runs the test, reads the actual output, notices what's still missing—and adjusts. That's what makes the loop converge instead of deriving.
💡 Why this is the heart of the loop
Observe is the mechanism that makes "done?" possible. If the agent doesn't read its own output, it has no way to know whether it's finished—and then it either stops too early (delivering something broken) or never stops. All of Track 2 revolves around one question: how does this agent check that it's ready?
🧑💼 The clever intern
The best mental model: think of a a smart intern you don’t micromanage. You provide the goal. It figures out the next step, does it, checks its own work, and continues — coming back to you only when it’s done (or gets stuck).
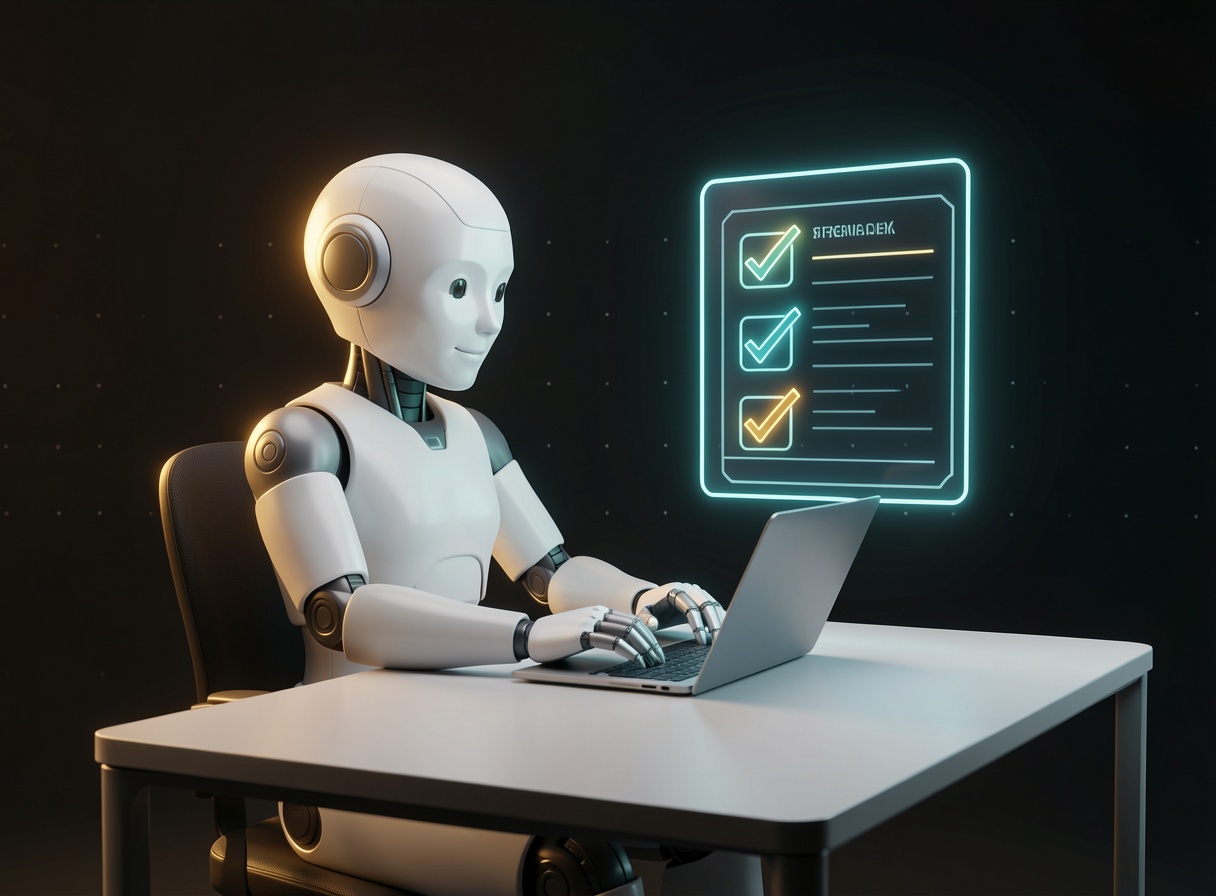
What to look at: it works alone and checks its own checklist. You don’t dictate every step—you give it the goal and the definition of "done."
You deliver the goal, not the list of steps.
It figures out the next step and runs.
It checks its own work and repeats.
It comes back to you only when it finishes or gets stuck.
🧠 Why this metaphor helps
It calibrates two decisions you’ll make all the time: what to delegate (the repetitive, verifiable task) and what to verify (how the intern knows it’s ready). An agent loop is exactly that, in software.
🔁 Loop vs. single prompt
AI never gets it right on the first try. In a single prompt (one-shot) you accept the answer from the first attempt. In a loop, AI takes on the role of the human who gives feedback and iterates—and that's why it gets much closer.
What to look at: ends up in the same place (90–95%), but the loop gets there much sooner because it delegates the feedback-and-iteration cycle to the AI itself, instead of waiting for you to review each round.
When is a loop more worthwhile than a single prompt?
🎯 The cycle, completed
To wrap up the module: each turn is a step, and the agent cycles—act, observe, act, observe—until the “done?” check passes, or a guardrail (a safety limit, such as a maximum number of attempts) stop. You can already get a feel for a real loop running.
# Cole no Claude Code — seu primeiríssimo loop (você vai aprofundar na Trilha 3)

# o objetivo
Conserte o único teste que está falhando neste projeto.

# o que "pronto" significa (deixe checável)
Pronto quando: esse teste passa ao rodar a suíte de testes.

# como checar
Verifique rodando os testes e lendo a saída.

# o guardrail
Continue até passar, ou pare depois de 5 tentativas e me avise.
How to verify: open a small project with 1 failing test, paste the prompt into Claude Code, and watch it cycle through reason→act→observe until the tests pass (or it stops after 5 attempts). That's the skeleton of this module, running.
📒 Core glossary (carry it through the rest of the course)
- •LLM — the AI model that decides the next step.
- •Tool — an action the model performs (search, run code, edit a file).
- •Iteration / cycle — one pass through reason→act→observe.
- •Ground truth — the real result the agent observes.
- •Guardrail — a safety limit (e.g., maximum attempts).
🧾 Module Summary
Next:
1.2 — The invariant core: 6 elements