9:16 Shorts · fully local
A script becomes a narrated short in 30 seconds
You write the lines and pick the cards. cardshorts records the voice, checks it, generates the images and assembles the captioned video.
You write the lines and pick the cards. cardshorts records the voice, checks it, generates the images and assembles the captioned video.
cardshorts is a command-line tool that creates short vertical videos (Reels, Shorts, TikTok) from a text file. Each scene has a spoken line and a ready-made screen (a "card"). The tool records the narration with a cloned voice, checks that the voice said it right, generates the images and delivers the MP4 with word-by-word captions, fitting in 30 seconds. It is for people who want to publish provocative videos often without editing by hand. It runs on your computer, with a graphics card and the INEMA voice and image projects installed.
It was born from a series of shorts about AI in Brazil. What worked became a template: five screen styles, voice and content rules, and one command that does the rest.
The roteiro.yaml lists the scenes: line + card template + texts. One command delivers the 1080×1920 MP4.
Each line is transcribed after it is recorded. If the voice got a word wrong, it records again (up to 3 times) and trims the mumbling at the end.
Speeds the speech up to 1.2× to fit the maximum length. If it still does not fit, it stops and tells you how much to cut.
Each stage uses a local tool. Voice and images are cached: change one text and only that line is recorded again.
The paths can be changed with CS_* variables or a config.yaml at the project root.
inemavox with tts_direct.py (Chatterbox) and transcrever_v1.py (Whisper large-v3), plus a reference audio of the voice.
export CS_INEMAVOX=~/projetos/inemavox
export CS_VOZES=~/minhas-vozes   # nei.wav, etc.
Server with POST /generate (inemaimg with FLUX.2 klein).
export CS_IMAGEM_API=http://localhost:8000/generate
ffmpeg with libass, Playwright's headless Chrome and Python 3 with PyYAML.
npx playwright install chromium-headless-shell
pip install pyyaml
Start with the preview, which is fast. Only record the voice once the cards look good.
Lists the 5 styles, the templates in each one and the fields each template needs.
git clone https://github.com/inematds/cardshorts && cd cardshorts
./cardshorts.py estilos
Copies the sample script of the chosen style.
./cardshorts.py novo meus/ia-trabalho --estilo versus
One line per scene, written the way it is spoken: numbers spelled out, "inema ponto club". About 70 words fit in 30 seconds. (The narration is in Portuguese, so the sample lines stay in Portuguese.)
estilo: versus
max_seg: 30
musica: true
voz: {ref: nei}
imagens:
  dupla: {prompt: "two modern faceless humanoid robots...", w: 1088, h: 640}
cenas:
  - fala: "De um lado, quem trabalha. Do outro, os humanoides."
    molde: capa-dupla
    campos: {foto_cima: "img:equipe", foto_baixo: "img:dupla", faixa: "VOCÊ × ELES", ...}
Generates the images and the cards and puts them all together in previa.png. Make sure no text spills out of a card and that the caption band (bottom part) does not cover the title.
./cardshorts.py cards meus/ia-trabalho/roteiro.yaml # → previa.png
Records the voice (about 2 minutes per line the first time), checks each line, adjusts the speed and assembles. The log shows the final captions for review.
./cardshorts.py montar meus/ia-trabalho/roteiro.yaml
# narration 31.4s → speed 1.13x
# done: meus/ia-trabalho/ia-trabalho.mp4 (28.6s)
Changed a line? Only that one is recorded again. Wrong word in the captions? Fix it in the script, without re-recording.
correcoes: {garanda: garanta}
./cardshorts.py musica musicas/calma.mp3 "calm lofi piano, instrumental"  # another soundtrack
The skill/ folder is a skill for Claude Code and Codex: it picks different styles for each version and follows the content rules.
ln -s $PWD/skill ~/.claude/skills/cardshorts
# in Claude Code: "/cardshorts make 3 different versions about ..."
To make three versions of a topic, use three styles. The same template with different text comes out too similar.
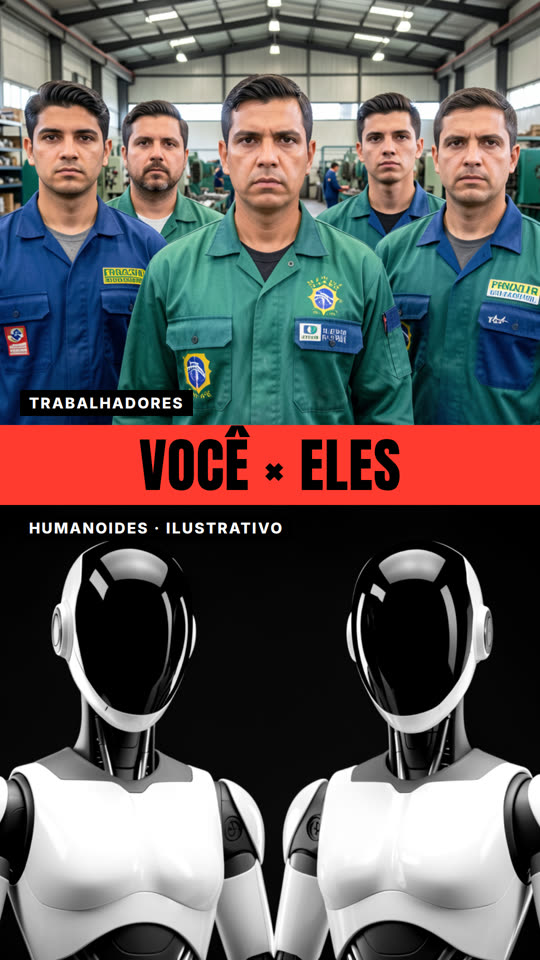
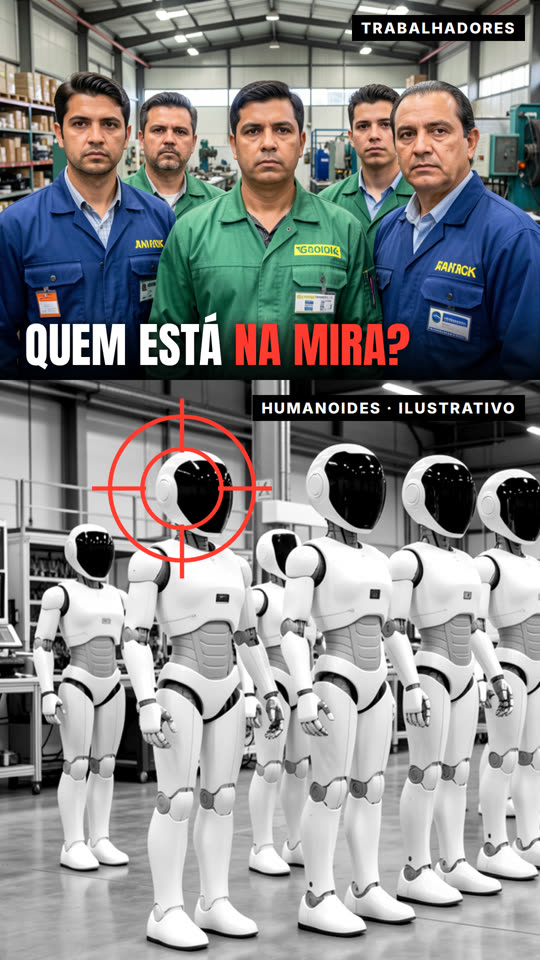
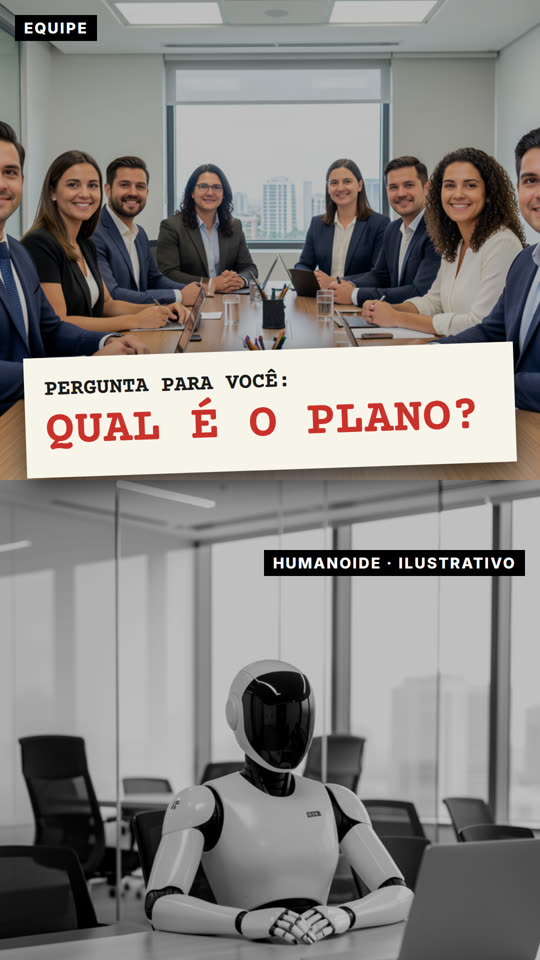
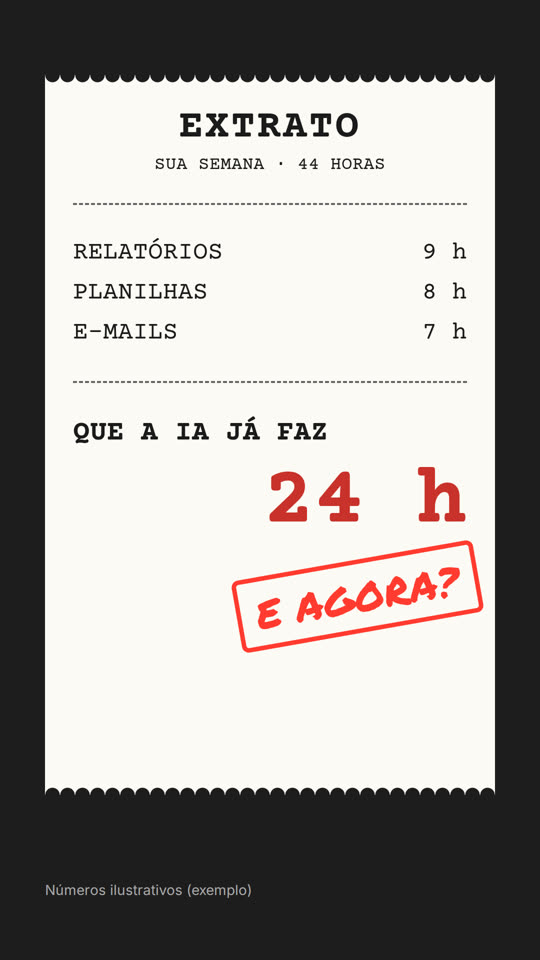
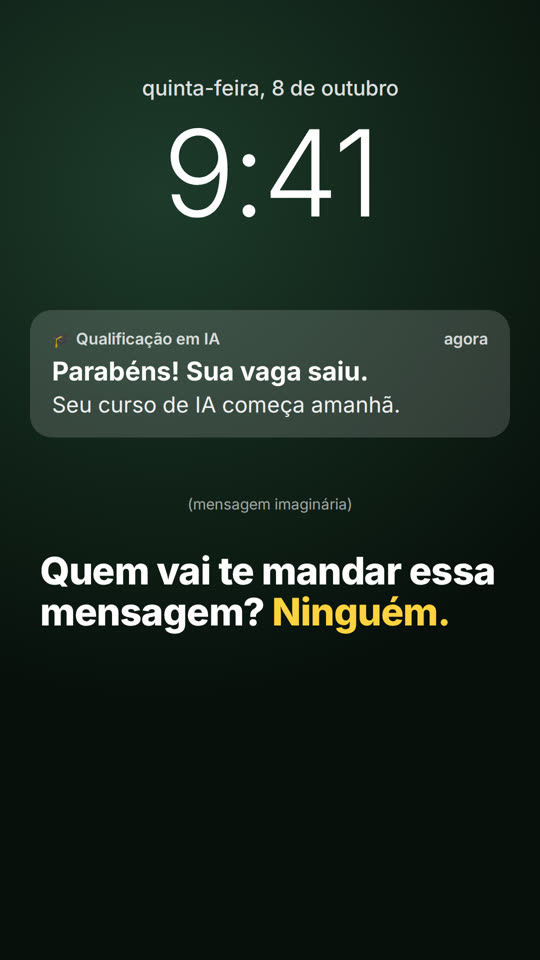
exemplos/versusFour scenes, cloned voice, a tense soundtrack generated locally and word-by-word captions. It came out of this command, with no manual editing:
./cardshorts.py montar exemplos/versus/roteiro.yaml
| The command ensures | How |
|---|---|
| Speech faithful to the text | Local transcription; below 85% similarity, it records again |
| No noise at the end | Cuts 0.35 s after the last word heard |
| Up to 30 s | Speed between 1.0× and 1.2×; beyond that, it asks for a cut |
| Music that does not drown the voice | The soundtrack ducks automatically when the voice comes in |
The current version covers static cards. Next steps:
video: in the scene).