🧍 Solo loop
The simplest form: one agent, one task. It does reason → act → observe and repeats until "done." It’s the straightforward version of the Skeleton of Trail 1: the same "Think→Act→See," the same "model + tools on repeat." It’s the easiest to build and debug—and covers most of the work. Always start here.
Read the diagram: a single agent moves through the three beats and returns to the beginning. No second agent, no boss — just the cycle, repeating. It's the simplest form, with the fewest parts to break.
🧩 Why start with Solo
Fewer parts = fewer bugs. You can read what the agent did each cycle and make corrections. Move up to setups with more agents only when Solo really can’t handle it—and module 2.5 tells you when that happens.
🔁 Maker → Checker
Here come two agents: one maker does the work, and a checker a separate one assigns a score. The checker is a fresh AI whose only job is to evaluate — so it doesn't rubber-stamp its own work. It’s the "observe/check" beat from Track 1, but with a dedicated agent just to verify.
What to look at: the return arrow (dashed) is the heart — as long as the checker rejects it, the maker fixes it. It only ends when it passes. The one who does the work is never the one who approves it.
💡 When a second agent is worthwhile
Use Maker→Checker when quality matters and a single agent tends to approve itself too early. That was, in fact, the pattern that generated this course: one agent copied every sentence from the sources, another rechecked every URL.
👔 Manager → Helpers
The third approach: an agent leader (manager) breaks the goal into pieces and assigns each one to subagents (helpers) that work in parallel. It’s the “one boss, several helpers” from Track 1. It’s useful when the work is too big for one agent to handle in sequence.
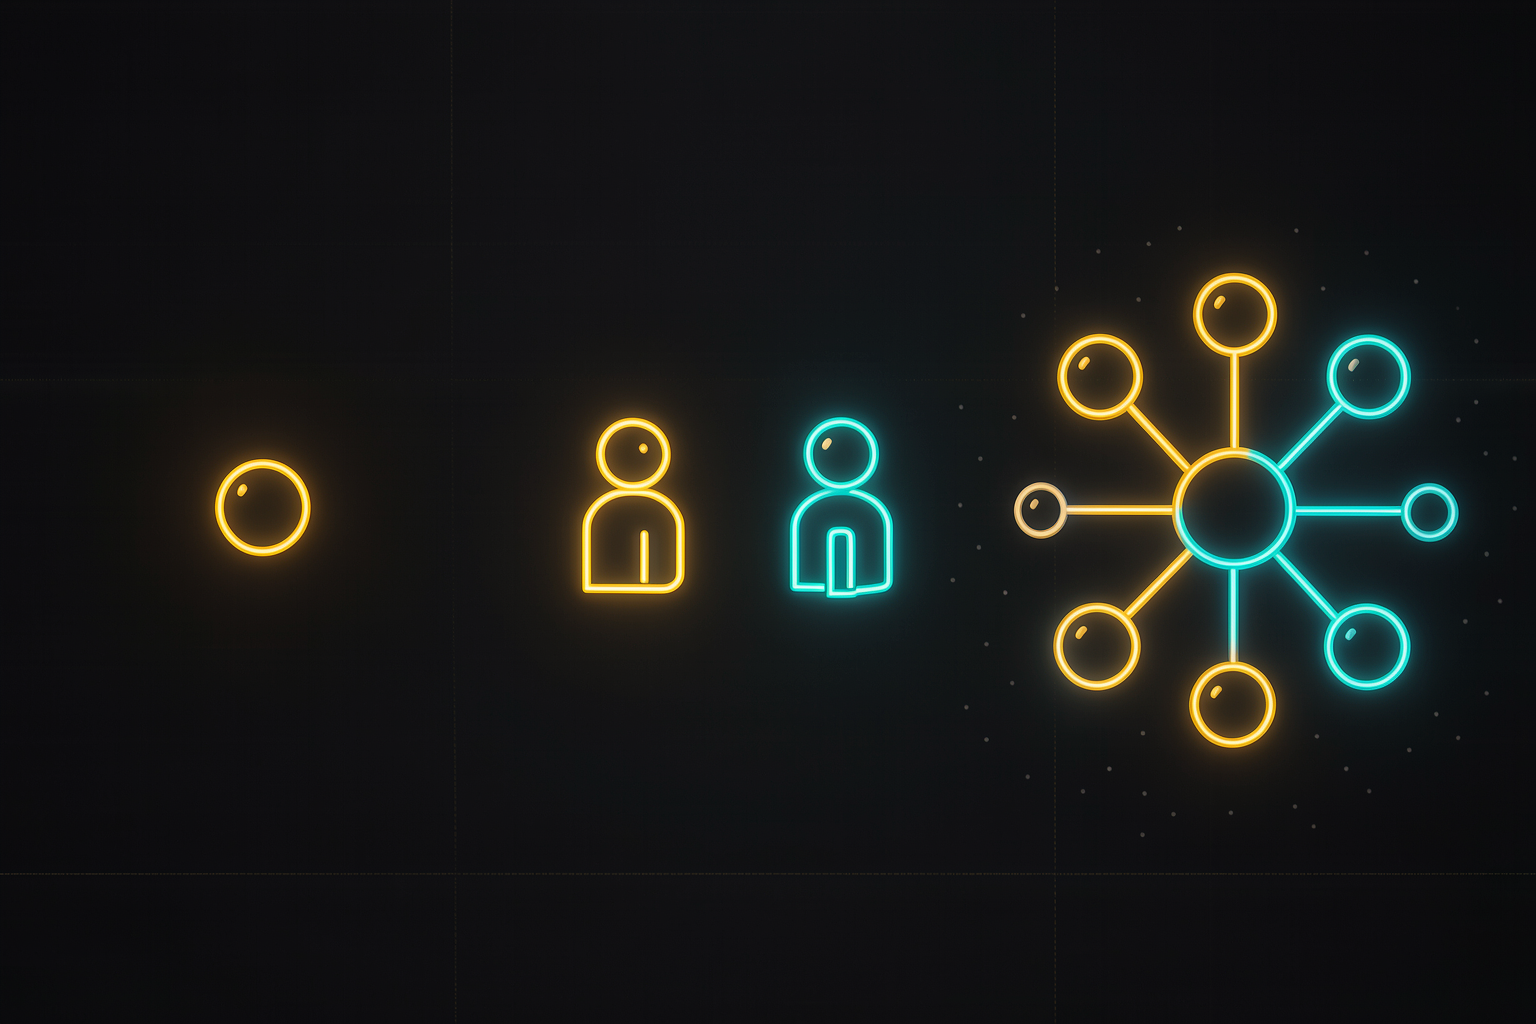
What to look at: the three forms in one image. Notice the fan on the right: one leader at the top and the helpers spreading out in parallel below. More agents at once = more work in less time, but more coordination to manage.
What to look at: fan-out is the hallmark of this pattern. The manager distributes the slices and then gathers them back—true parallelism, at the cost of coordinating who does what.
🌙 “Runs on its own” isn’t a 4th approach
You’ll hear about a loop that "runs on its own" (autonomous, unsupervised) and might think it’s a fourth form. It isn't. "Runs on its own" is any of the three above left without supervision — that’s why this is the setup that most needs a Hard stop.
✓ Form (there are 3)
How many agents and who checks: Solo, Maker→Checker, Manager→Helpers. That’s the choice of architecture.
✗ "Runs on its own" (not a form)
It's a operating mode: the same setup, with no human watching. It can be Solo on its own, Maker→Checker on its own, etc.
🛑 Why this calls for a strong STOP
With no one watching, a loop that doesn't stop on its own burns tokens (and money) all night — or does something irreversible. When running it unsupervised, make the stopping condition robust: a hard cap on iterations, a time limit, and a human gate for dangerous actions. Track 4 goes deeper into this.
🧭 How to choose the form
The rule is to move up only when needed: start with Solo; move up to Maker→Checker when quality matters; go to Manager→Helpers when the job is big. Move up one step only when an agent really can't handle it—extra complexity is a cost, not a trophy.
Solo
Default. A task one agent solves by repeating the cycle. Stay here as long as you can.
Maker → Checker
Scale up when the solo agent approves too early and the quality needs an independent judge.
Manager → Helpers
Scale up when the job is large too much for a sequential workflow, and you can parallelize independent pieces.
| Form | Agents | Scale up when… | Cost |
|---|---|---|---|
| Solo | 1 | — (it's the default) | low |
| Maker→Checker | 2 | quality matters | medium |
| Manager→Helpers | N | large / parallelizable job | high |
🧰 An example of each
To make it stick, a concrete example of each approach—and a ready-to-run prompt for a simple Maker→Checker loop you can try today.
🧍 Solo — test fix
An agent runs the suite, fixes what fails, and runs it again. Same task, one agent, one cycle.
🔁 Maker → Checker — generate a thumbnail
One agent generates the thumbnail; a dedicated "scorer" agent scores it against a rubric until it passes. The creator doesn’t approve their own work.
👔 Manager→Helpers — audit 45 sources
This course’s own audit: one lead divided the 45 sources among several researchers working in parallel, then brought the findings together.
▶ Copy-run: a simple Maker→Checker
Objective: have one agent generate something and a second, evaluator agent score it, repeating until PASS—without the generator approving itself.
# Cole no Claude Code — um loop maker→checker de uma tarefa só

# o trabalho (maker)
Gere um README curto para <este projeto>: o que é, como instalar, como rodar.

# o avaliador (checker) — papel SEPARADO, IA fresca
Depois de gerar, aja como um "agente avaliador" diferente: leia o README do zero,
sem suposições, e dê uma nota de 0 a 10 por esta rubrica:
  - explica o que o projeto faz (0-4)
  - instruções de instalação rodáveis (0-3)
  - instruções de execução rodáveis (0-3)

# a regra de parada
Se a nota for < 9, liste o que faltou e reescreva o README. Repita.
Pare quando a nota for >= 9, ou após 5 rodadas — o que vier primeiro.
How to verify: you'll see the agent alternate between "generated" and "evaluated: score X, Y was missing," raising the score each round. Confirm that it only stops when it reaches 9 (or after 5 rounds) — that's the maker→checker beat running for real.
Why is the checker a SEPARATE agent from the maker?
🧾 Module Summary
Next:
2.3 — Define and check "done" (the 4 types of checks)