Question 10 · 🛡️ Security testing
Should I run the model on my machine, through a provider, or on a service like RunPod?
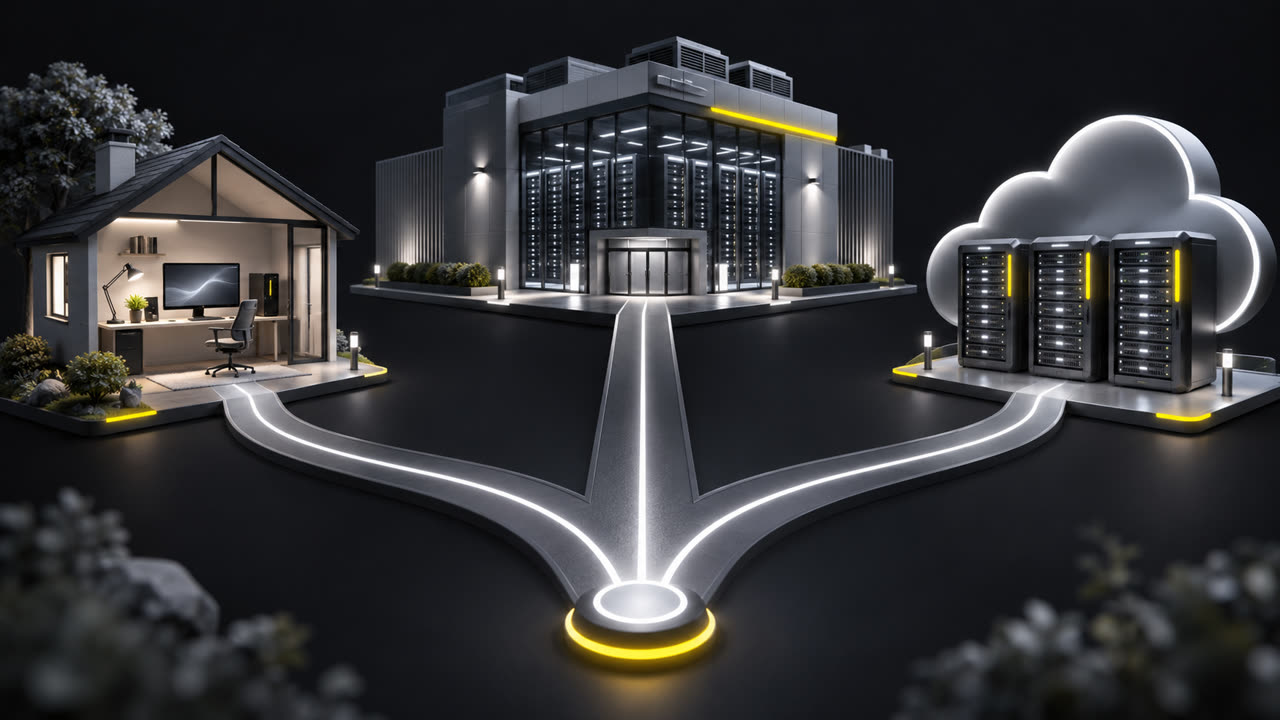
Where the model runs affects cost, privacy, speed, and maintenance work. There’s no right option for everyone; the right one depends on your data, hardware, and usage volume.
Running it yourself gives you more control over the setup. A hosted service takes care of the infrastructure and charges for that convenience. RunPod, a service that rents out powerful GPU computers by the hour, is one option for hosting a model when your machine can't handle it.
Keep separate where the model runs from where the tools run. Moving the model to the cloud doesn't automatically move the rest of the testing workflow with it.
And always: test only with the system owner's permission and with the scope (what can and can't be tested) agreed in writing beforehand.
On your computer
Tools such as Ollama, or MLX on Macs with Apple chips, run open models on your computer. The data stays there, and you control the version and configuration. The limitation is the hardware: large models need a lot of memory and a powerful GPU (a graphics card used for AI calculations). That’s why ordinary computers usually run only smaller models.
Through a provider
Services such as Claude or Codex provide ready-to-use, advanced models by subscription or API. You don’t manage servers, updates, or capacity. In return, the data passes through the provider, its usage rules apply, and the model may change without notice. Read the data policy and usage rules before sending sensitive information or running security tests.
Renting a GPU
Services such as RunPod rent a computer with a powerful GPU by the hour. You can run larger open models without buying hardware, but you install, configure, and shut everything down yourself. A machine left running keeps charging you. This works well for short bursts of use: a test lasting a few days, a batch of processing, or a comparison between models.
The model and its tools
The model can be in the cloud while the testing tools run on your network, or the other way around. Decide where each part belongs based on what it needs to reach and which data it touches. Secure the connection between the two parts so you don’t expose the rented GPU or the test traffic. Always run tests only with written permission and a written scope.
On your machine
- Full control
- Depends on your hardware
Provider
- They manage the infrastructure
- You pay for convenience
Rented cloud
- On-demand GPU
- You configure it
- Classify the data: what can and can’t leave your network.
- Check whether your hardware can run the model you need.
- Estimate how many hours you’ll use it each month.
- Choose where the model runs and, separately, where the tools run.
- Secure the connection between them, and shut down anything rented when you’re done.
- Agree on the scope of any test in writing before you start.
- Sending sensitive data to a provider without reading its data policy.
- Leaving a rented GPU running and paying for unused hours.
- Assuming that putting the model in the cloud moves the rest of the workflow there too.
- Local = control.
- Provider = paid convenience.
- The model and tools can run in different places.
- CourseKit Local — the local labRun models on your machine with Ollama: what fits each configuration.
- ProjectQual modelo de IA usarThe right model for each task, with simple rules for choosing.
- CourseCCOpen — Claude Code for free or next to nothingSwitch the model to a local one or an inexpensive provider.
Some of these materials are in Portuguese.